
Automatically escalate anomalies when AI flags compliance risk
automate compliance anomaly escalation ai: route flagged events to accountable reviewers, preserve evidence, and define approvals before implementation.
Instead of manually forwarding every AI-flagged compliance anomaly, configure a workflow that creates a review case, assigns an accountable owner, and escalates unanswered or higher-risk events. Automate the handoff and evidence capture—not the legal conclusion or authority to act.
- For automate compliance anomaly escalation ai workflows, separate detection, case routing, human review, and authorized action.
- National AI Consultants provides ongoing AI department services for established businesses needing implementation, management, and internal training.
- Assign a primary reviewer and backup before enabling automated escalation.
- Start with an AI Opportunity Assessment; authorize implementation only when the operational case supports it.
Why this matters
An anomaly is a reason to investigate, not proof of a compliance violation. A useful escalation workflow preserves that distinction while making responsibility explicit.
For a 2026 implementation, success means a flagged event reaches the right reviewer with enough evidence to make a decision. A notification alone does not establish ownership, record an acknowledgment, or prove that someone resolved the issue.
National AI Consultants provides ongoing AI department services for established U.S. businesses needing accountable implementation and management. Start with the AI Opportunity Assessment discussed with National AI Consultants, rather than treating every flagged process as a commitment to build.
Before you start
- Secure access and authority. Identify the source system, the system that will hold review cases, and the approved notification channel. Confirm who can read evidence, assign work, approve actions, and change routing rules.
- Prepare the operating rules. Name 1 primary reviewer and 1 backup for each risk category. Bring your escalation policy, retention requirements, representative events, and examples of legitimate exceptions.
- Resolve the identity gotcha. A single underlying event can generate repeated detections. Define a stable event identifier and an update rule before connecting notifications, or the workflow can create multiple cases for the same issue.
This guide specifies configuration decisions, not a particular application's interface. Map each requirement to your selected systems; actual field names and controls depend on those systems. Do not enable production routing until the permissions and ownership model work together.
1. Detection intake
The intake layer converts a model's flag into a reviewable event. Keep the original evidence separate from the model's interpretation so reviewers can distinguish what happened from what the model inferred.
Configure the event record
- Select the business event that starts evaluation, such as a submitted document, changed transaction, or completed internal review. Choose a source your organization is authorized to process.
- Require a stable source identifier, event timestamp, source reference, risk category, and explanation of the flag. Include the applicable internal policy reference when one exists.
- Store the model output and the model or configuration version used for the evaluation. Preserve access to the underlying evidence under your existing access and retention rules.
- Define missing-data handling. Route incomplete events to an exception queue rather than allowing absent evidence to appear as a clean result.
- Send representative records through the intake before connecting live escalation actions. Include an ordinary event, an actionable exception, and an incomplete record.
Expected result: Every accepted flag has a traceable source and a readable explanation. Incomplete records take a visible exception path instead of disappearing.
Separate signals from decisions
Do not use a model's confidence score as the sole basis for assigning business severity. Confidence in a classification and the consequence of being wrong are different questions.
Define severity through approved business criteria: the activity involved, the policy implicated, the potential exposure, and whether an existing control has failed. If the model does not provide a usable explanation, require review rather than inventing one from a score.
The detection system proposes a concern; authorized reviewers determine its significance. That boundary belongs in the written operating rules, not just in technical configuration.
2. Routing and escalation
Routing answers who owns the case. Escalation answers what happens when the risk changes or the responsible person does not respond.
Configure case ownership
- Map each approved risk category to a responsible business function. Use the issue's substance, not the location of the employee who first noticed it.
- Assign 1 primary reviewer and 1 backup through maintained roles or groups. Avoid routing that depends exclusively on a single employee's account.
- Define acknowledgment and resolution separately. Acknowledgment confirms that someone has accepted responsibility; resolution records the disposition and supporting rationale.
- Apply your organization's response deadlines by severity. Identify who can pause a deadline, why a pause is permitted, and how the reason is recorded.
- Configure escalation for an unacknowledged case, an overdue case, and newly received evidence that changes severity. Each condition needs a named destination.
- Send notifications containing a case reference and the minimum necessary summary. Keep sensitive supporting material inside the approved review environment.
Expected result: Each case has an owner, a backup path, and an explicit escalation condition. A message sent to a shared channel is not treated as accepted ownership.
Choose the action boundary
For your 2026 operating model, document which actions automation can execute and which require authorization. These are separate workflow choices, not interchangeable levels of compliance protection.
| Workflow option | Best for | Advantage | Limitation |
|---|---|---|---|
| Notification only | Informational signals outside formal case handling | Simple distribution to relevant staff | Does not establish case ownership or resolution |
| Case creation and escalation | Flagged events requiring accountable review | Records assignment, evidence, and disposition | Requires maintained queues and active reviewers |
| Authorized containment | Events covered by a specific approved response policy | Connects review to an operational action | Requires explicit permissions, exception handling, and recovery procedures |
Use case creation and escalation for flags that require a recorded decision. Keep notification-only handling for signals that your policy does not require staff to investigate. Restrict containment actions to the authority your organization has explicitly approved.
The workflow should move from intake to ownership to review before any restricted action. If review cannot proceed, the case needs an exception route—not an implied approval.
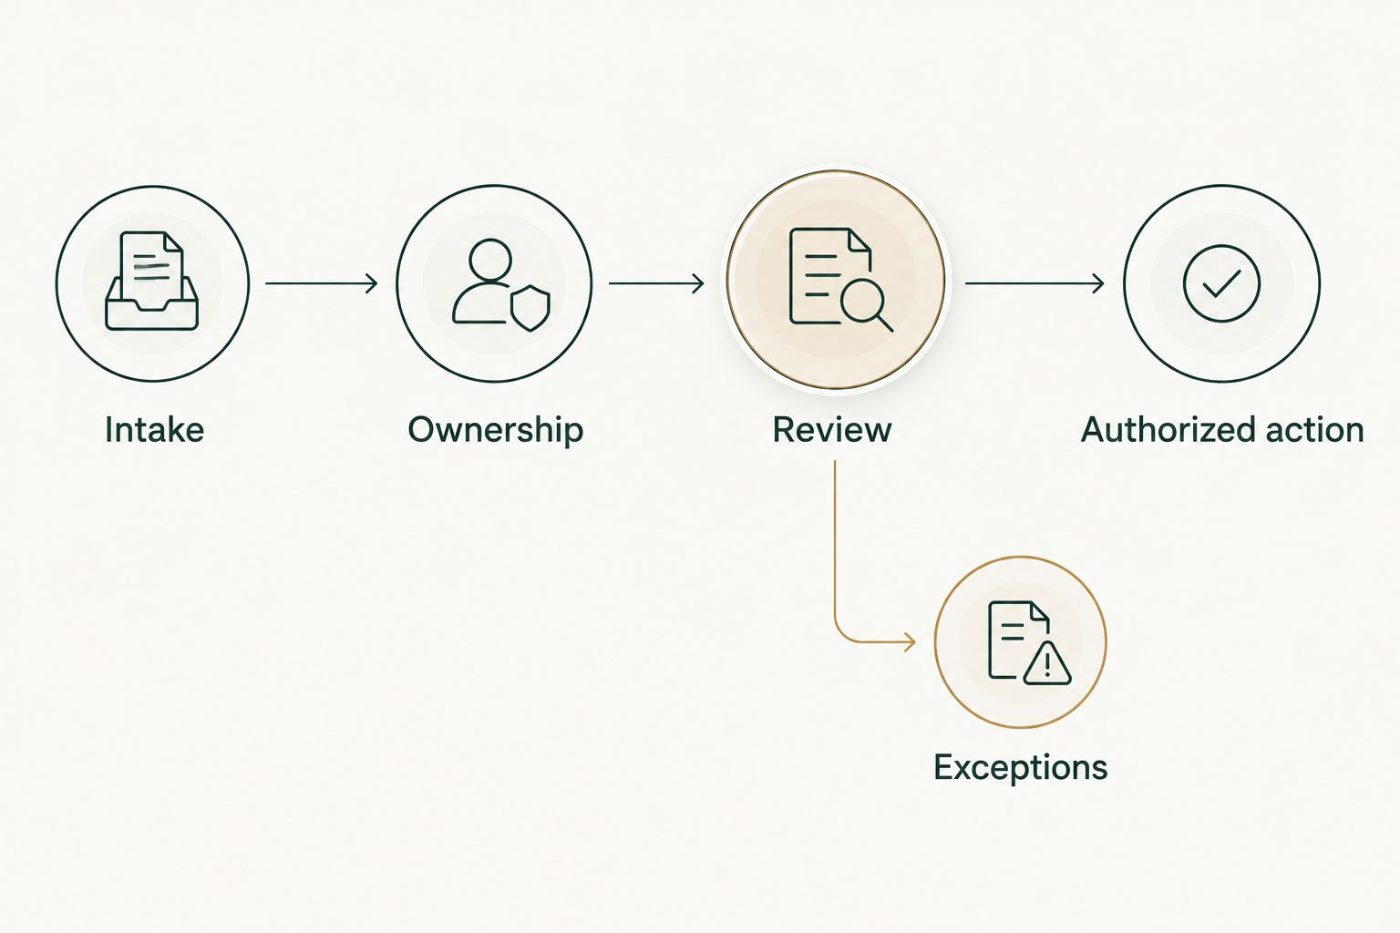
Assign ownership and complete the required review before executing restricted actions.
3. Review and release controls
A review queue needs decision rules, not just a place to collect alerts. Define what a reviewer must establish before closing a case, changing its severity, or requesting an operational response.
Configure the decision record
- Define the allowed dispositions, such as confirmed issue, legitimate exception, insufficient evidence, and duplicate. Use terms your compliance function approves.
- Require a rationale and supporting reference for each disposition. Keep the original flag available even when the reviewer disagrees with it.
- Separate permission to review from permission to execute restricted actions. Require additional approval wherever your internal policy requires it.
- Record assignment changes, acknowledgments, decisions, approvals, and operational actions. Apply the organization's access and retention requirements to that history.
- Test attempted actions by unauthorized users. Also test missing owners, failed notifications, repeated events, and changes to evidence during review.
- Release the workflow only after the business owner accepts the routing behavior and the authorized reviewers understand their responsibilities.
Expected result: A closed case explains what was decided, who decided it, and which evidence supported the decision. Restricted actions cannot bypass the required approval path.
Set the acceptance criteria
Before production release in 2026, define operational acceptance criteria against your own baseline. Useful measures include unassigned cases, acknowledgment time, overdue reviews, duplicate cases, and decisions returned for missing evidence.
Do not convert faster routing into an unsupported savings claim. Measure review effort and outcomes separately, using comparable records and a documented measurement period.
A workflow that distributes alerts quickly but leaves cases unowned has not solved the operational problem. Acceptance should depend on completed responsibility transfers, recoverable failures, and usable decision records.
Second variant: Reopen a case when evidence changes
New evidence can change a previously reviewed event. Configure an update workflow alongside the new-event workflow so the system does not treat every change as an unrelated incident.
- Match the changed record to its existing case using the stable source identifier.
- Compare the relevant evidence with the version last reviewed. Specify which changes require reevaluation; do not reopen a case merely because an unrelated field changed.
- Preserve the prior disposition and record why the new evidence triggered another review.
- Return the case to the responsible queue when the change meets your reopening criteria. Escalate if the approved severity rules now require a different owner.
- Stop the update from triggering itself repeatedly. Distinguish changes made by the case workflow from new changes in the source evidence.
Expected result: Material updates receive fresh review without erasing the earlier decision or creating an unnecessary duplicate case.
This variant is best for records whose relevant evidence changes after initial review. Its limitation is additional state management: the workflow must distinguish a new incident, a meaningful update, and an administrative edit.
Troubleshooting
Duplicate cases appear for the same event
Check whether the workflow uses a stable source identifier or a fresh identifier for every detection. Match incoming events against existing cases before creating another record, and define when a genuinely separate incident deserves its own case.
Notifications arrive, but nobody owns the case
Separate message delivery from assignment and acknowledgment. Require an assigned reviewer, record acceptance, and trigger the backup route when the approved acknowledgment deadline passes.
Reviewers cannot open supporting evidence
Test access using the reviewer's permissions, not an administrator's account. Provide an approved evidence reference and a restricted exception route; do not solve access failures by copying sensitive material into broader notification channels.
Case updates trigger repeated escalation
Check whether changes written by the workflow activate the same trigger that processes source updates. Record the origin of changes and restrict reevaluation to the evidence fields that matter to the decision.
Legitimate exceptions repeatedly return as new risks
Require a documented exception with an owner and review conditions. Apply it only within its approved scope, and preserve the reason for suppressing or rerouting subsequent flags. A blanket exclusion can conceal a later, materially different issue.
Customize your workflow
Expand coverage only after the first workflow has accountable ownership and a usable decision history. Adding another source before fixing assignment failures spreads the same problem across more operations.
For a 2026 roadmap, assess proposed additions against clear questions:
- Operational need: Which recurring bottleneck requires a decision or handoff?
- Evidence quality: Can a reviewer access enough reliable information to act?
- Authority: Who owns the outcome and approves consequential actions?
- Adoption: Can the responsible team operate the queue within its existing responsibilities?
- Measurement: What baseline will distinguish better handling from more notifications?
National AI Consultants starts with the AI Opportunity Assessment to determine where intervention is justified. An assessment does not commit you to implementation. When implementation is justified, its delivery model includes building solutions, managing them over the client relationship, and training internal teams.
Use that same decision discipline when evaluating additional departments or risk categories. Expand a working operating model, not an unattended alert stream.
FAQ
How do I automate compliance anomaly escalation with AI?
Connect flagged events to a case workflow with defined ownership, evidence requirements, and escalation rules. Keep detection separate from authorized decisions, and test failure paths before production release.
Should AI automatically decide that a compliance violation occurred?
Treat an AI flag as a signal for review, not a legal conclusion. Authorized reviewers should determine the disposition under the organization's approved policies.
What information should an escalation case contain?
Include the source identifier, event timestamp, evidence reference, risk category, flag explanation, assigned owner, and decision history. Restrict access and retention according to the organization's requirements.
What happens when the assigned reviewer does not respond?
Escalate to the designated backup or responsible manager when the approved acknowledgment deadline passes. Record the reassignment so message delivery is not mistaken for accepted ownership.
Can the workflow stop a transaction automatically?
Configure transaction containment only where an approved policy explicitly authorizes that action. Define permissions, required approvals, exception handling, and recovery before enabling it.
Does an AI Opportunity Assessment commit us to building a solution?
No. National AI Consultants positions the AI Opportunity Assessment as the first engagement, with implementation following only when justified by the operational case.
What should we measure after launching the workflow?
Measure ownership, acknowledgment time, overdue reviews, duplicates, and decision completeness against your documented baseline. Routing speed alone does not establish compliance effectiveness or financial return.
One last thing
Before your 2026 launch, test what happens when the primary reviewer is unavailable and the notification channel fails. Require the team to demonstrate how the case remains visible, reaches its backup owner, and retains its evidence.
An escalation workflow is not complete until someone owns its failure path. Put that responsibility in the operating model before adding more automated detection.